Shipped
TCP visual moat — three test looks
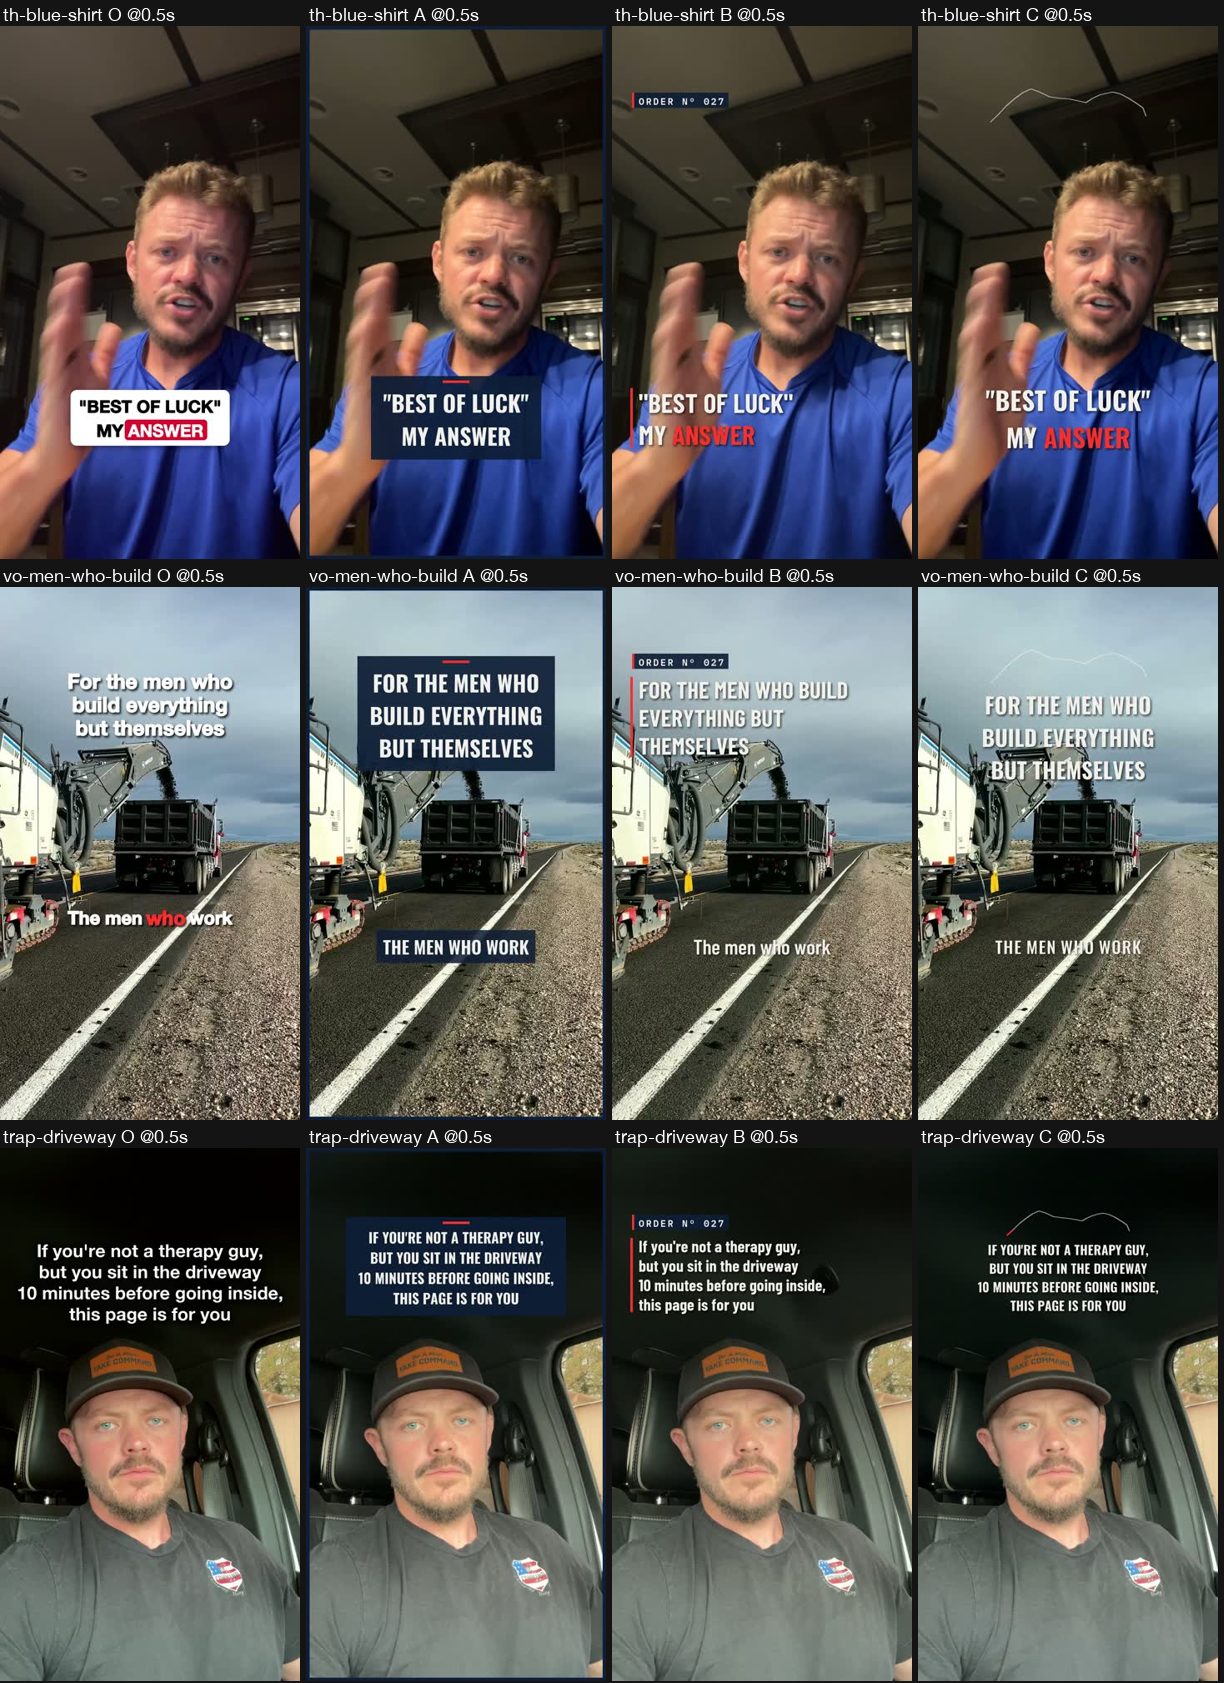
Each row is one finished reel. The first video is what shipped. A, B and C are the same edit, same words, same audio, re-skinned in one of three looks. They play muted, the way most people first see a reel in the feed. Ask yourself one thing per look: would you know it's a TCP reel in half a second with the sound off?
NEW D = your combo (Nov 2): B's left-locked text and red line on the left, on A's navy box made mostly see-through. Captions sit in the same see-through box, and the word being said turns red with a short bounce. The Order tab is gone from every look, B included. A = Command Frame (the cover look carried into the reel). B = Field Order (left-set hook, red line, film grain). C = Ridge Line (your real ridge as a line that fills red as the reel plays). Tests only. Nothing here is posted or scheduled.
Nov 2: D is now the default look on every new reel, for now (under the never-worse rule). Reels already scheduled keep their old look. See D on YouTube (LFYT6 v3) →
1. Talking head — "Best of luck" (blue shirt)
D Your combo
A Command Frame
B Field Order
C Ridge Line
2. Voiceover b-roll — "For the men who build everything but themselves"
Shipped
D Your combo
A Command Frame
B Field Order
C Ridge Line
3. Trap reel — "If you're not a therapy guy…" (driveway)
Shipped
D Your combo
A Command Frame
B Field Order
C Ridge Line
The trap text had to get smaller in every look (46–54 px against 64 px on the shipped reel) so the extra pieces fit above your cap. That is a real readability cost on trap reels.
The half-second test (frame at 0.5 s, all twelve)
Your profile grid in each look (9 covers, cropped to the grid box)
Today
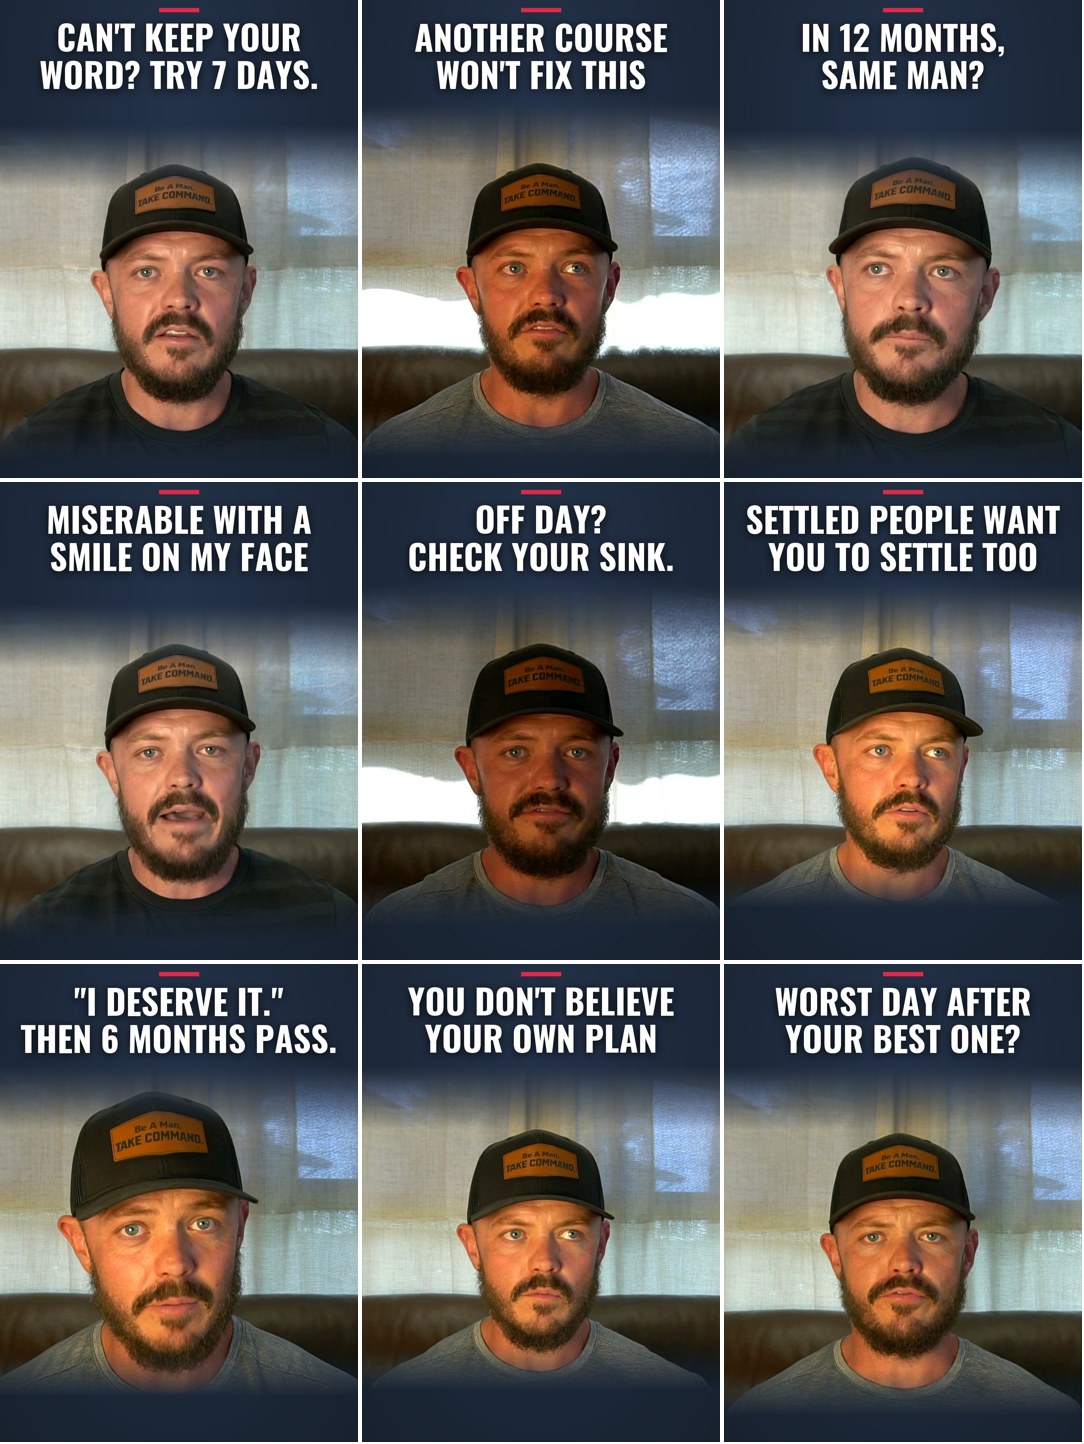
D Your combo
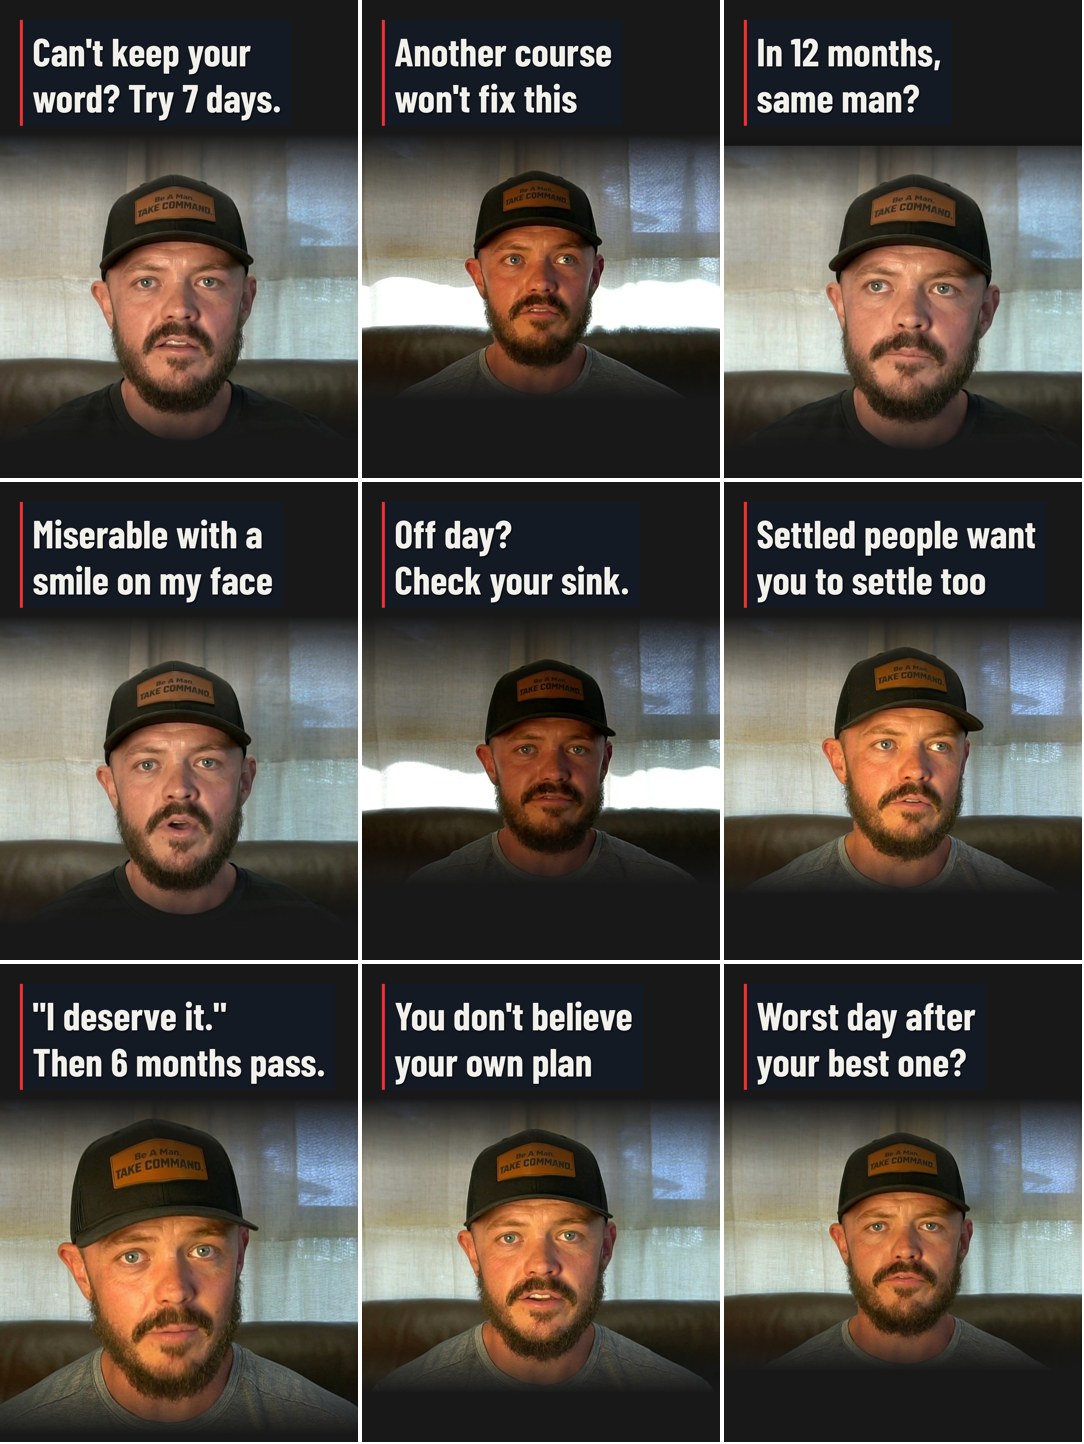
A Command Frame
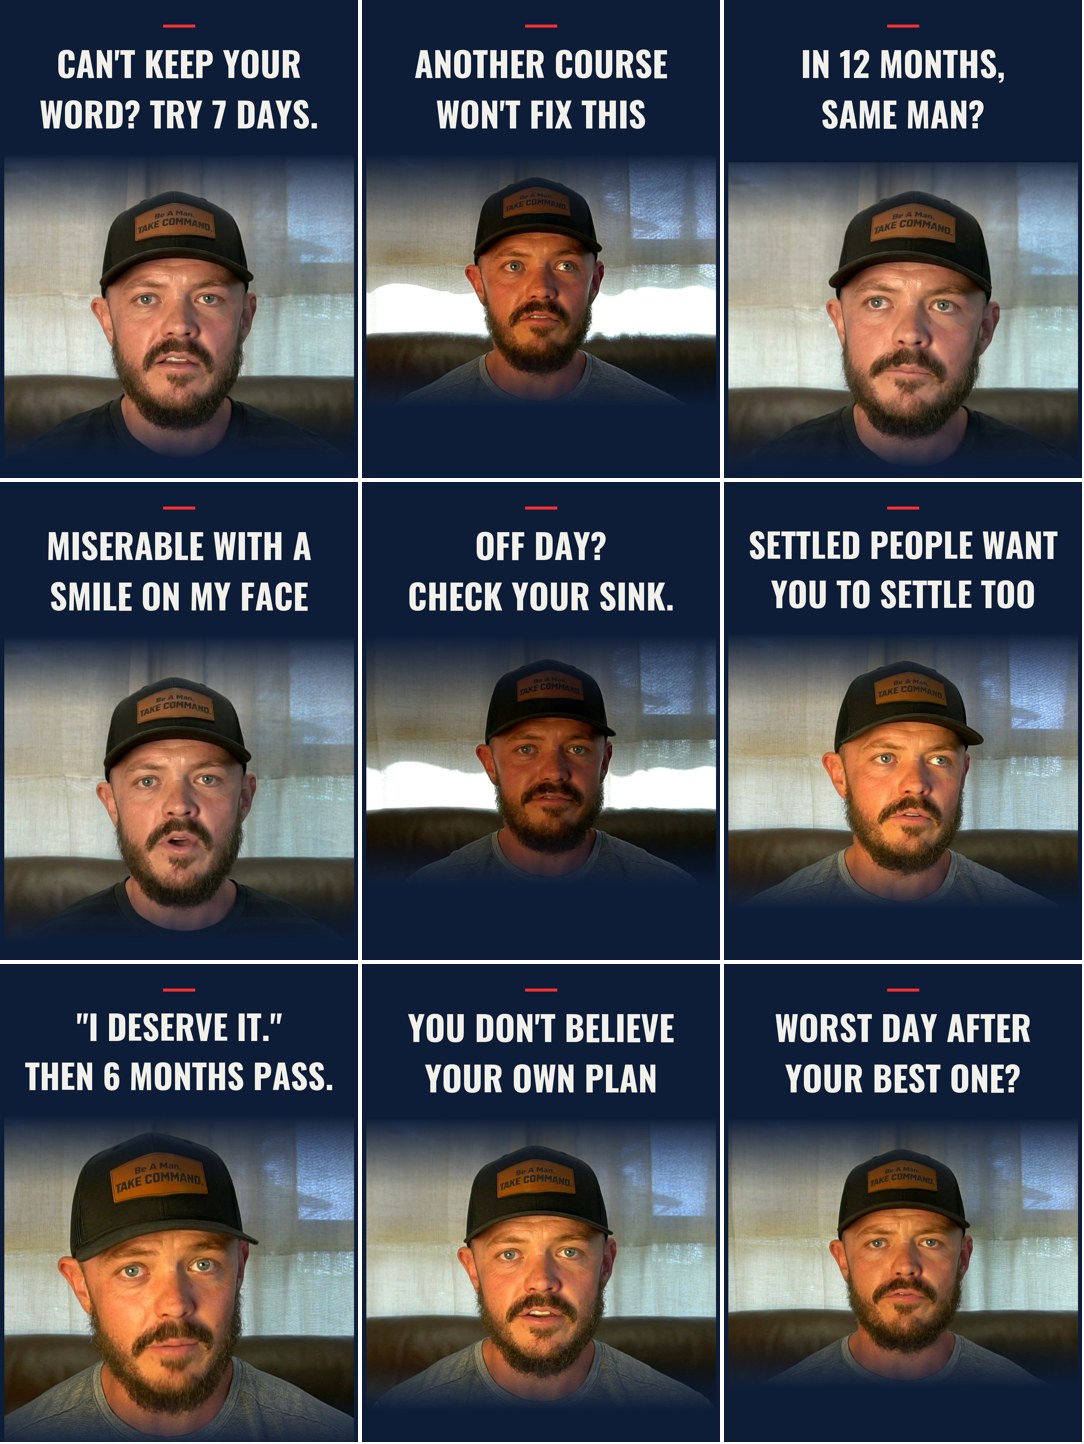
B Field Order
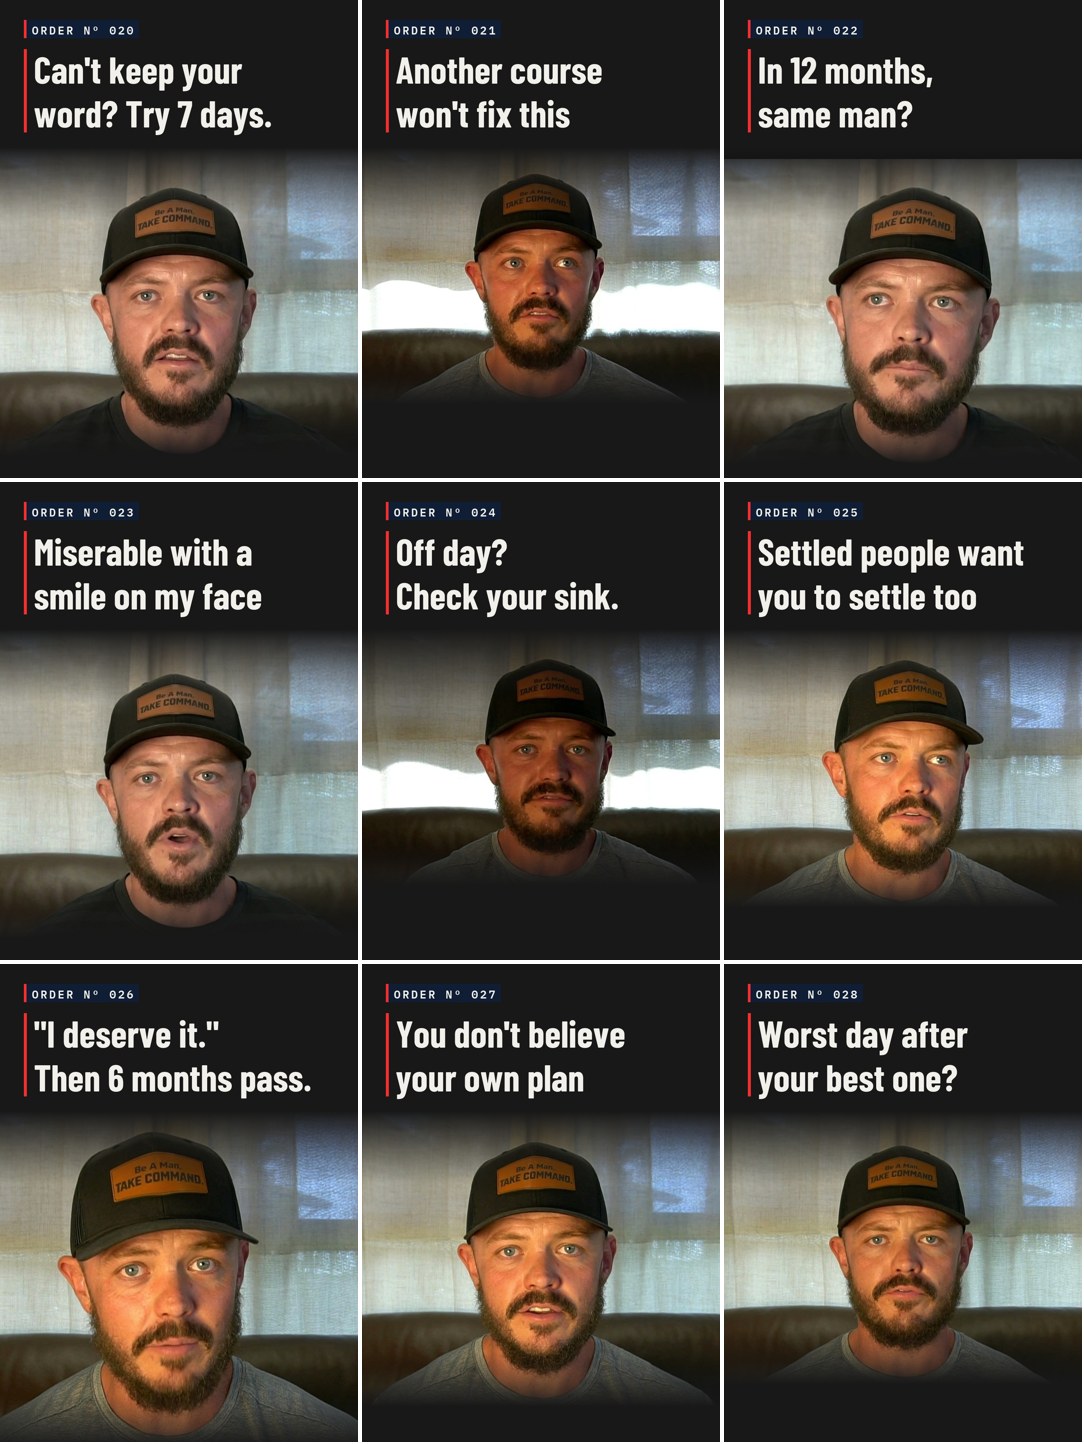
C Ridge Line
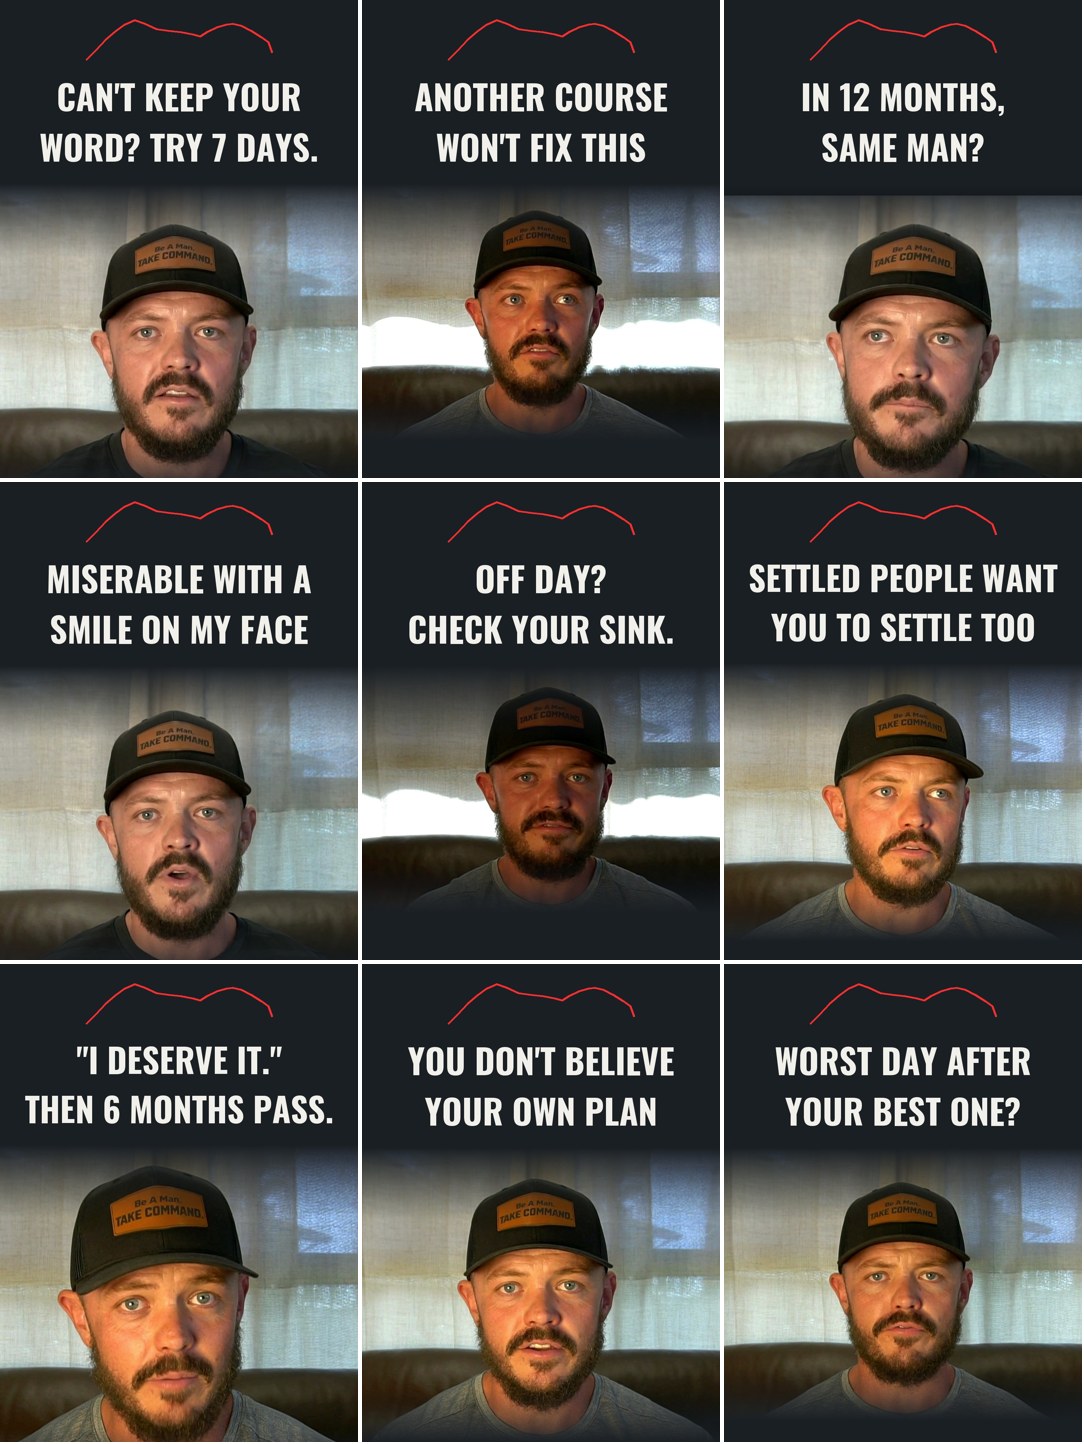
How they scored
Readability was measured by having the Mac read the captions off the video every half second. On the talking head, the shipped reel's captions were read for 69 of 110 spoken words; A, B and C each got 71. On the voiceover reel the shipped version got 77 of 102; A got 79, B 78, C 76. So none of the looks made the captions harder to read. The hook was read in full at half a second in every version except C on the voiceover reel, where white text over a bright sky lost 2 of 8 words.
A is the easiest to recognise because it is the same navy, red bar and Oswald type as your covers, so feed, grid and reel finally match. B is the most distinct from other creators but its tab is small. C is the most "you" in idea, but the line is thin, and on a handheld talking head it has to fade out whenever your head moves into its spot (6 times out and back in 41 seconds), which is busy. Full write-up: TCP-VISUAL-MOAT on the Mac.
Built Nov 2 2026 by the visualmoat job. Pick one to test on a few new reels; nothing changes in the real pipeline until you say so.